

Updated October 2026: I re-tested the RADIUS-unreachable critical VLAN and auth-fail VLAN behavior in my home lab on IOSv-L2 15.2 with FreeRADIUS 3.0.27 and an EAP-TLS client, including deadtime ALIVE/DEAD cycling while the daemon stayed stopped. Details are in the new section before What's Next. I did not re-test ISE or Catalyst 9300 hardware: the SW9300 and ISE outputs and GUI steps above are illustrative examples, not captures from my lab.
Impact and Urgency
When the RADIUS server is unreachable, the impact on a production access layer switch is immediate and broad. Every port configured with authentication port-control auto is affected. New authentication attempts fail. Re-authentication timers that fire during the outage fail. Depending on how the switch is configured to handle server-dead conditions, endpoints may lose network access entirely, remain in their current VLAN, or be placed in a Critical VLAN.
(This article is part of the PingLabz 802.1X series - the full 802.1X guide maps the whole cluster in reading order.)
In a campus building switch with 48 access ports, a RADIUS outage affecting all ports simultaneously is a P1 incident. The diagnostic sequence needs to be fast and methodical.
Confirming the Switch Has Marked ISE Dead
SW9300# show aaa servers
Illustrative sample output from a Catalyst 9300 with ISE marked dead (not captured in my lab):
RADIUS: id 1, priority 1, host 10.0.0.10, auth-port 1812, acct-port 1813
     State: current DEAD, duration 00:04:22, previous duration 3d14h
     Dead: total time 262s, count 3
     Platform State from SMD: current DEAD, duration 00:04:22, previous duration 3d14h
     Platform Dead: total time 262s, count 3
     UP/DOWN: #times 4, #failed transitions 0
     Authentication: #sent 1876, #received 1614
     Retransmission: #sent 262, #late responses 0, #bad responses 5
     Estimated Outstanding Access Transactions: 0
Key fields:
State: current DEAD - ISE is currently unreachable from this switch's perspective.
Dead: total time 262s, count 3 - the server has been declared dead three times total, for a combined 262 seconds. count 3 in a single shift suggests an intermittent connectivity issue rather than a clean outage.
Retransmission: #sent 262 - the switch retransmitted 262 RADIUS packets before giving up. A ratio of retransmissions to total sent (262/1876 = 14%) indicates a significant packet loss or latency issue.
#bad responses 5 - ISE sent responses that failed authentication validation (likely shared secret mismatch, since a wrong shared secret causes HMAC verification to fail).
SW9300# show aaa dead-criteria radius 10.0.0.10 auth-port 1812
Illustrative sample output (not captured in my lab). On my IOSv-L2 lab switch, this exact command defaulted the accounting port to 1646 and missed a server configured with acct-port 1813, so give both auth-port 1812 acct-port 1813 if your server uses 1813:
RADIUS: id 1
Dead Criteria Details for Server 10.0.0.10/1812:
     Configured Retransmits:        3
     Configured Timeout:            5
     Estimated Outstanding Transactions:        0
     Dead Detect Interval:        7
     Computed Dead Detect Moves:        4
     Dead Detect Interval:        30
     Current State:        DEAD
     Time Server has been Dead:        4 min 22 sec
Dead detection is not a fixed wall-clock failover. On my IOSv-L2 re-test, aggressive dead-criteria plus deadtime produced DEAD→ALIVE→DEAD cycling while the daemon stayed stopped — tune criteria and deadtime together rather than assuming a single 15-second number.
Step 1: Basic Connectivity Test
The first question is whether the switch can reach ISE at all.
SW9300# ping 10.0.0.10 source Vlan99 repeat 10
Illustrative sample output - reachable:
Type escape sequence to abort.
Sending 10, 100-byte ICMP Echos to 10.0.0.10, timeout is 2 seconds:
Packet sent with a source address of 10.0.99.1
!!!!!!!!!!!!!
Success rate is 100 percent (10/10), round-trip min/avg/max = 2/3/5 ms
Illustrative sample output - unreachable:
Type escape sequence to abort.
Sending 10, 100-byte ICMP Echos to 10.0.0.10, timeout is 2 seconds:
Packet sent with a source address of 10.0.99.1
..........
Success rate is 0 percent (0/10)
Source Vlan99 is critical. The switch sends RADIUS packets from whatever interface is specified in ip radius source-interface. If you ping without specifying source, the ping uses the routing table's best source, which may succeed even though RADIUS-sourced packets from Vlan99 cannot reach ISE. Always source the ping from the same interface as RADIUS traffic.
If ping fails:
Check routing:
SW9300# show ip route 10.0.0.10
Verify there is a route to ISE. In a campus topology, ISE at 10.0.0.10 should be reachable via the default route or a specific route through the core switch.
SW9300# show ip route 0.0.0.0
If there is no default route and no specific route to the ISE subnet, RADIUS packets are black-holed. Add the route or verify the routing protocol is distributing the ISE subnet correctly.
Check the source interface:
SW9300# show running-config | include source-interface
ip radius source-interface Vlan99
Verify Vlan99 is up:
SW9300# show interface Vlan99
Vlan99 is up, line protocol is up
  Hardware is Ethernet SVI, address is 1c6a.7ae0.1234 (bia 1c6a.7ae0.1234)
  Internet address is 10.0.99.1/24
If Vlan99 is down, the switch has no source IP for RADIUS packets. Fix the VLAN 99 interface first.
Step 2: Test UDP Reachability on RADIUS Ports
ICMP success does not guarantee UDP 1812/1813 reachability. A firewall may pass ICMP but block RADIUS ports.
SW9300# test aaa group ISE-SERVERS test-user badpassword new-code
Illustrative sample output from an IOS XE switch when RADIUS is working (not captured in my lab):
Attempting authentication test to server-group ISE-SERVERS using radius
User authentication request was rejected by server.
On my IOSv-L2 lab switch this test was not a reliable signal. With FreeRADIUS stopped and the server marked DEAD, test aaa still printed User rejected, while show aaa servers counted reject 0. Treat "rejected" from test aaa as a real Access-Reject only when the reject counter in show aaa servers goes up, or a capture or the RADIUS server log shows the reject. A server that never answered means the user was not authenticated, not that the server rejected it:
test aaa group radius test-user badpassword new-code
User rejected
     State: current DEAD, duration 3s, previous duration 13s
             Response: accept 1, reject 0, challenge 6
Illustrative sample output when the RADIUS port is blocked (not captured in my lab):
Attempting authentication test to server-group ISE-SERVERS using radius
User was not authenticated.
No response from ISE - the test times out. This means the RADIUS packet left the switch but ISE never responded. Either the firewall blocked UDP 1812, ISE's RADIUS service is down, or the packet never reached ISE.
To differentiate between a firewall block and an ISE service failure, check ISE directly.
Step 3: Check ISE Health
Navigation: Administration > System > Deployment
Check the status of all ISE nodes. Each PSN (Policy Service Node) should show "In Service." A node showing "Out of Service" or with a red indicator has a service failure.
Navigation: Administration > System > Health Summary
This dashboard shows CPU, memory, and disk utilization for each ISE node. ISE marking RADIUS requests as failed - while technically reachable - can happen when ISE is overloaded:
- CPU > 90% sustained: ISE cannot process RADIUS requests fast enough, causing switch timeouts
- Memory > 90%: ISE services may crash or become unresponsive
- Disk > 80% on /opt/CSCOcpm: ISE logs fill disk, causing service instability
Navigation: Operations > Troubleshoot > Diagnostic Tools > Network Device RADIUS Diagnostic
Enter the switch's IP address (10.0.99.1) and click "Run." This tool checks whether ISE has a matching Network Device entry for that IP, whether the shared secret is configured, and whether the RADIUS service is able to receive requests.
Check the ISE RADIUS service status via CLI on ISE (if you have CLI access):
show application status ise
Look for radius service status. If the RADIUS service is stopped, restart it:
application start ise
Step 4: Shared Secret Mismatch
A shared secret mismatch can present as "unreachable": the server receives the packets but cannot validate them, so it silently drops them. The switch gets no response, retransmits, and eventually marks the server dead. (This lab stopped the server rather than breaking the secret, so I did not re-test this case here.)
The tell-tale sign: #bad responses in show aaa servers output. RADIUS bad responses occur when ISE sends a response but the switch cannot verify the Message-Authenticator attribute (because the shared secret is wrong on one side).
Also check ISE: if ISE drops packets due to shared secret mismatch, it logs:
Navigation: Operations > RADIUS > Live Logs
Look for entries from the switch IP that show no matching Network Device (Failure Reason "11007 - Could not locate Network Device or AAA Client"). Note that in Cisco's ISE event codes 11001 is simply "Received RADIUS Access-Request", not a shared-secret error. ISE was not part of my lab, so this comes from Cisco's documentation, not a capture.
On the switch, re-enter the shared secret:
SW9300(config)# radius server ISE-PRIMARY
SW9300(config-radius-server)# key <RADIUS_KEY>
On ISE: Administration > Network Resources > Network Devices > [Device] > Authentication Settings > Shared Secret - retype the shared secret. Save.
After changing on both ends, test immediately:
SW9300# test aaa group ISE-SERVERS test-user badpassword new-code
Step 5: Verify Network Device Definition in ISE
ISE only responds to RADIUS requests from devices explicitly listed in its Network Device database. If the switch's source IP is not in ISE's Network Device list, ISE drops all RADIUS requests from that switch.
Navigation: Administration > Network Resources > Network Devices
Verify:
- A Network Device entry exists for this switch
- The IP address in the entry matches the switch's
ip radius source-interfaceaddress (10.0.99.1 in this lab) - The RADIUS Authentication Settings are enabled with the correct shared secret
- The entry is not associated with a Network Device Group that has been excluded from policy
If the switch's management IP recently changed (common after re-IP projects), the old IP in ISE's Network Device entry will cause all RADIUS requests to be silently dropped.
Step 6: Critical VLAN Behavior During Outage
While troubleshooting the RADIUS outage, confirm that connected endpoints are in an appropriate state. If the switch is configured for Critical VLAN fallback:
SW9300(config-if)# authentication event server dead action reinitialize vlan 50
SW9300(config-if)# authentication event server alive action reinitialize
Endpoints on ports with this configuration move to VLAN 50 (Critical VLAN) when the server is unreachable. That is intentional, but VLAN 50 only gives whatever access VLAN 50 has. The switch does not limit it to DNS and DHCP for you, so give the critical VLAN its own ACL or firewall policy that allows only what endpoints should reach during an outage. In my lab I verified the VLAN 50 placement and ping reachability, not those restrictions.
Check current port states:
SW9300# show authentication sessions
Illustrative sample output from a Catalyst 9300 during a RADIUS outage (not captured in my lab). My IOSv-L2 lab switch printed a different format: Authorized, with a CRITICAL_AUTH_VLAN service template and VLAN 50 (see the re-test below):
Interface  MAC Address     Method  Domain  Status        Fg  Session ID
Gi1/0/1    a4b1.c2d3.e4f5  N/A     UNKNOWN Auth-Critical     0A0063010000002C
Gi1/0/2    b5c2.d4e5.f6a7  N/A     UNKNOWN Auth-Critical     0A0063010000002D
Gi1/0/3    c6d3.e5f6.a7b8  dot1x   DATA    Authorized         0A0063010000002E
Auth-Critical status means the endpoint is in Critical VLAN mode (the switch-initiated fallback). The Authorized entry on Gi1/0/3 is a session that was already authenticated before the outage - the existing session remains active.
When ISE comes back up, ports with authentication event server alive action reinitialize trigger a re-authentication automatically. Monitor this with:
SW9300# debug authentication all
None of this behavior is safe to rehearse on a production switch, which is the argument for keeping a throwaway copy of the same chain. Standing up 802.1X against your own RADIUS server gives you a switch and a server you can break deliberately: stop the daemon, watch show aaa servers flip to DEAD, start it again, all without a change window.
Step 7: Deadtime and Recovery Tuning
After marking a RADIUS server dead, the switch enters a deadtime period during which it does not attempt to contact that server. This prevents the switch from flooding a recovering ISE with pent-up requests.
SW9300# show running-config | include deadtime
radius-server deadtime 15
Default deadtime is 0 (no deadtime - the switch retries the dead server immediately). This can cause thundering herd problems when ISE recovers after a long outage. A deadtime of 15 minutes gives ISE time to stabilize before the switch resumes sending requests.
To configure:
SW9300(config)# radius-server deadtime 15
During the deadtime period, the switch does not send authentication requests to the dead server. If a secondary RADIUS server is configured, all traffic goes to the secondary. If there is no secondary, new authentication attempts fail until the deadtime expires.
For redundant ISE deployments, see Article 28 - RADIUS Redundancy and Failover in 802.1X Deployments for the full configuration with multiple PSNs and tuned failover parameters.
Troubleshooting
Symptom: Switch shows ISE as DEAD but ISE reports normal operation and other switches are authenticating fine
Cause: The specific switch cannot reach ISE due to a port ACL, VLAN ACL (VACL), or route issue affecting only this switch's management VLAN. Other switches on different management subnets are unaffected.
Fix: Narrow the scope. Confirm the management VLAN and source interface for this switch:
SW9300# show running-config | include source-interface
ip radius source-interface Vlan99
SW9300# show interface Vlan99 | include Internet
  Internet address is 10.0.99.1/24
Check for any ACL applied to Vlan99 (illustrative output):
SW9300# show ip interface Vlan99 | include access list
  Inbound  access list is MGMT-ACL-IN
  Outbound access list is not set
Review the ACL for rules blocking UDP 1812/1813 outbound or UDP responses inbound:
SW9300# show ip access-lists MGMT-ACL-IN
If an inbound management ACL blocks the RADIUS replies, add a permit before the deny-all. Match the server's source port, not the destination port: in my lab the Access-Accept went from 10.57.99.10:1812 to the switch's 10.57.99.1:1645, so a rule written as any eq 1812 would not match the reply. An illustrative example for the addresses above (I did not test this ACL):
SW9300(config)# ip access-list extended MGMT-ACL-IN
SW9300(config-ext-nacl)# permit udp host 10.0.0.10 eq 1812 any
SW9300(config-ext-nacl)# permit udp host 10.0.0.10 eq 1813 any
Symptom: RADIUS works initially after a switch reload but fails after several hours - ISE shows the switch making authentication requests from an unexpected IP
Cause: The ip radius source-interface Vlan99 is configured correctly, but a DHCP-assigned IP on another interface (perhaps a routed port or Out-of-Band management port) becomes the preferred source for RADIUS packets after routing table changes during uptime. ISE's Network Device entry does not include this alternate IP, so ISE drops the requests.
Fix: Verify the source interface is consistently used. Check show aaa servers and note the IP ISE is seeing requests from. Compare to the switch's ip radius source-interface setting. If routing changes are causing the source IP to shift, make the management VLAN interface the only viable source by ensuring ip radius source-interface is set and the VLAN99 interface is always up. Also check for any no ip radius source-interface in the configuration that might be overriding the global setting.
As a defensive measure, add the alternate IP to ISE's Network Device entry as a secondary address, or use a network device group with a subnet range:
Navigation: Administration > Network Resources > Network Devices > [Device] > IP Address
Change from a single IP to an IP range or add the alternate IP as an additional entry.
Symptom: ISE is reachable and shared secret is correct, but show aaa servers shows high retransmission count (>5%) and intermittent DEAD declarations
Cause: ISE is overloaded or the network path between the switch and ISE has packet loss. The switch sends RADIUS requests, ISE processes them but responds slowly, and the switch times out and retransmits before the response arrives.
Fix: First check ISE health at Administration > System > Health Summary. If CPU or memory is high, investigate which ISE service is consuming resources. Profiling, posture, and pxGrid can all spike CPU during large endpoint onboarding events.
Second, check the network path for packet loss:
SW9300# ping 10.0.0.10 source Vlan99 repeat 500 size 512
A 500-ping test with larger payload (512 bytes, closer to RADIUS packet size) reveals intermittent packet loss that a 10-ping test misses.
Third, tune the RADIUS timeout and retransmit on the switch to be more tolerant of slower ISE responses:
SW9300(config)# radius server ISE-PRIMARY
SW9300(config-radius-server)# timeout 10
SW9300(config-radius-server)# retransmit 3
Increasing timeout from 5 to 10 seconds gives ISE more time to respond before the switch marks it as non-responsive.
Verifying Recovery
After fixing the underlying issue, confirm ISE transitions from DEAD back to UP:
SW9300# show aaa servers
The server state should show current UP. The UP/DOWN: #times counter increments with each state transition - this counter tells you the total number of times ISE has been declared dead since the switch last reloaded.
Force re-authentication on affected ports to clear Critical VLAN state:
SW9300# clear authentication sessions
This clears all sessions and forces re-authentication. Use with caution in production - it briefly disrupts all authenticated endpoints on the switch.
To clear only the Critical VLAN sessions without disrupting already-authenticated sessions:
SW9300# clear authentication sessions interface GigabitEthernet1/0/1
Repeat for each port showing Auth-Critical status. Ports will re-authenticate through ISE and receive their correct VLAN assignment.
Re-tested in my home lab (October 2026)
Built in my home lab with an IOSv-L2 15.2 switch (not a Catalyst 9300) and FreeRADIUS 3.0.27 (not ISE). The client used wired EAP-TLS. Normal VLAN 20, critical VLAN 50, auth-fail VLAN 60. I did not re-run the Catalyst and ISE steps above.
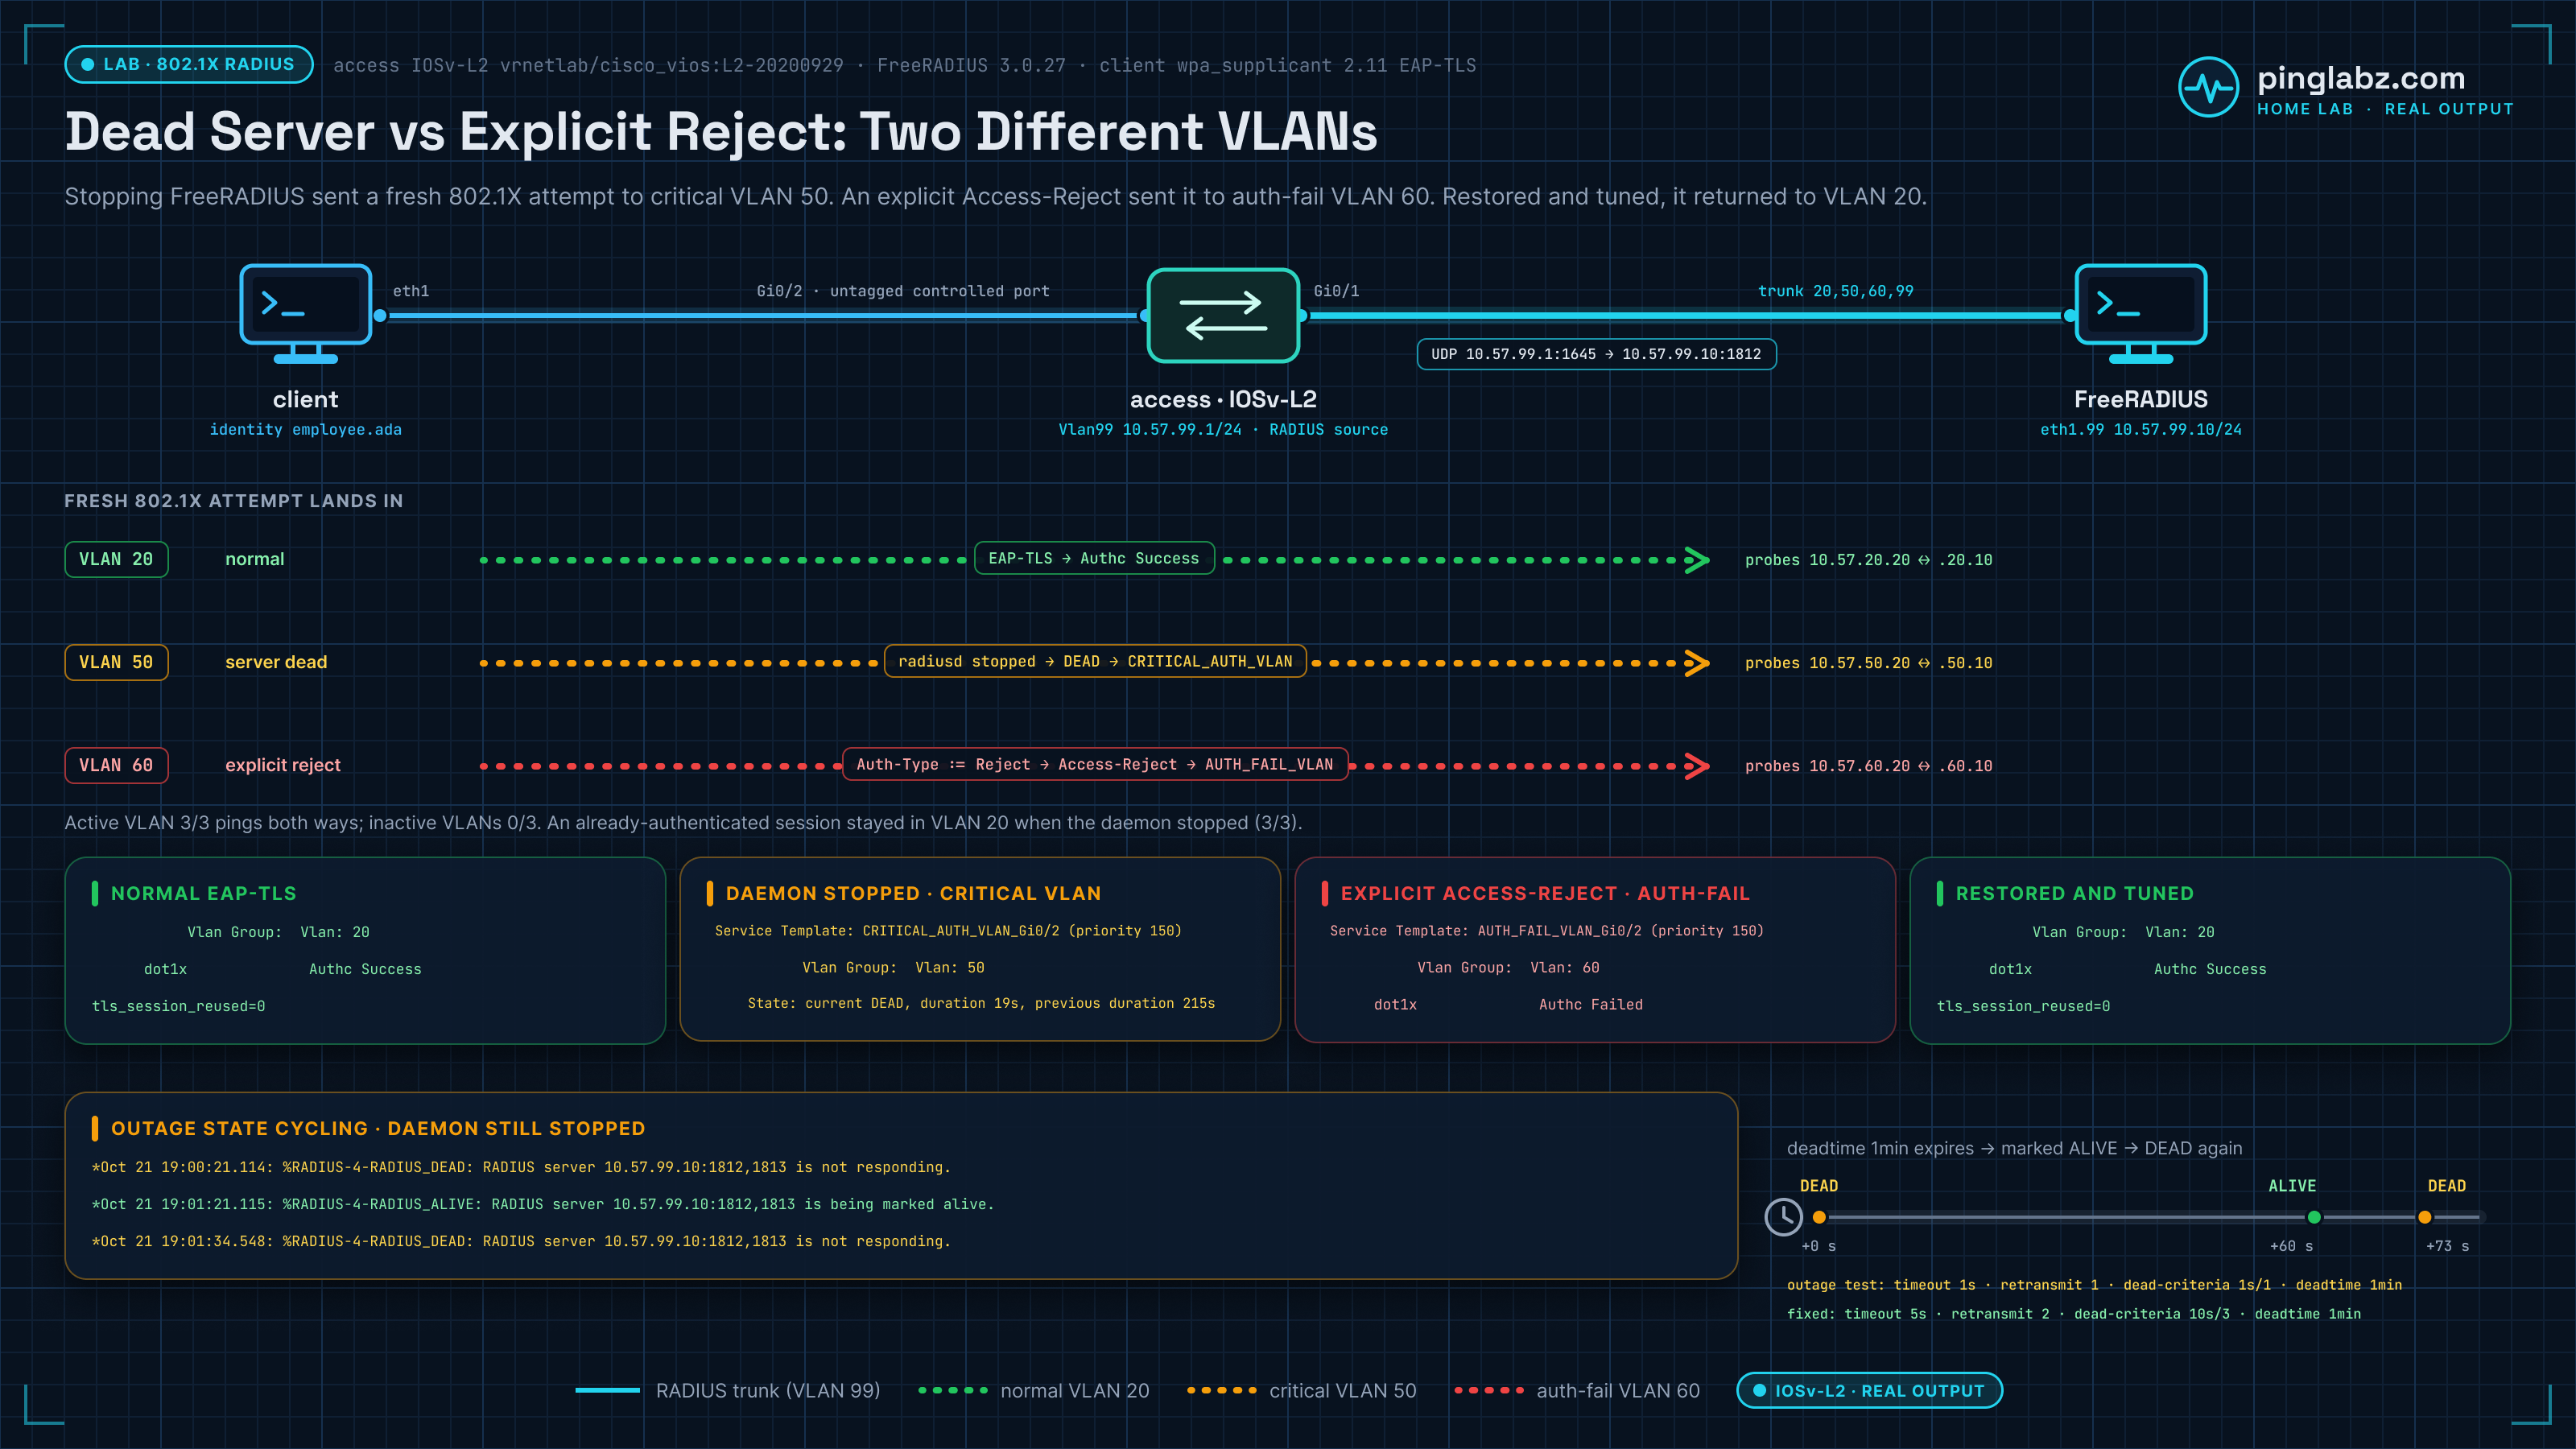
Working EAP-TLS baseline
Authorized on VLAN 20 with a fresh TLS session:
           Vlan Group:  Vlan: 20
      dot1x              Authc Success
tls_session_reused=0
Wire direction on the accept (auth UDP 1812; NAS source port 1645 on this image):
(6) Sent Access-Accept Id 7 from 10.57.99.10:1812 to 10.57.99.1:1645 length 190Break it: stop FreeRADIUS
An already-authorized VLAN 20 session kept passing traffic after radiusd stopped. A fresh authentication with aggressive dead-criteria landed in critical VLAN 50 with the server DEAD:
	Service Template: CRITICAL_AUTH_VLAN_Gi0/2 (priority 150)
           Vlan Group:  Vlan: 50
     State: current DEAD, duration 19s, previous duration 215s
While the daemon stayed down, deadtime produced ALIVE→DEAD cycling in syslog — do not read a brief ALIVE as "service restored":
*Oct 21 19:00:21.114: %RADIUS-4-RADIUS_DEAD: RADIUS server 10.57.99.10:1812,1813 is not responding.
*Oct 21 19:01:21.115: %RADIUS-4-RADIUS_ALIVE: RADIUS server 10.57.99.10:1812,1813 is being marked alive.
*Oct 21 19:01:34.548: %RADIUS-4-RADIUS_DEAD: RADIUS server 10.57.99.10:1812,1813 is not responding.
Different path: explicit Access-Reject
With the server up but configured to reject the user, the port used auth-fail VLAN 60 — not the critical VLAN:
	Service Template: AUTH_FAIL_VLAN_Gi0/2 (priority 150)
           Vlan Group:  Vlan: 60
      dot1x              Authc Failed
Fix: restore and tune
Restored FreeRADIUS and milder dead-criteria (timeout 5, retransmit 2, dead-criteria time 10 tries 3); fresh auth returned to VLAN 20:
           Vlan Group:  Vlan: 20
      dot1x              Authc Success
tls_session_reused=0
Accounting port on this image (use the full show that prints it):
    Acct Port : 1813
    Dead Detect Time         : 10s
What's Next: Article 23 - Dynamic VLAN Assignment Not Working in 802.1X: Troubleshooting Guide - covers the specific failure scenarios where RADIUS and ISE are reachable and authentication succeeds, but the endpoint lands in the wrong VLAN or the native VLAN instead of the assigned one.