
Active/standby failover on the Cisco ASA is the simplest high-availability mode the platform supports: two physically identical firewalls connected by a dedicated failover link, one unit forwarding traffic, the other watching and waiting. When the active unit dies, the standby promotes itself in under a second and inherits every IP and MAC address of the formerly-active. To users, traffic flows continue with at most a single dropped packet. This article walks through the full configuration, the show commands you read to verify it, and the few gotchas that bite on real builds. Every config block below was tested as part of building the PingLabz ASA reference lab; lab-specific constraints are noted at the end.
If you are pairing this with stateful sync (so existing TCP sessions also survive failover), the next article in the cluster is stateful failover and interface tracking. If you are diagnosing a failover problem - both units active, neither active, slow promotion - skip ahead to common outage scenarios for the split-brain section.
What Active/Standby Failover Actually Does
Two ASAs share a failover link (a directly-connected layer-2 link, dedicated to failover communication) and a failover key (a shared secret authenticating the protocol). Both units boot, the primary becomes Active, the secondary becomes Standby Ready. The active unit owns every configured IP - the standby's data interfaces have a separate "standby" IP that nothing actually uses for traffic. Failover hellos go over the failover link; the standby unit also monitors layer-2 interface state.
When the active unit fails - power loss, kernel panic, monitored-interface down, or no failover hello received within the holdtime - the standby:
- Detects the failure (within ~3 seconds at default polltimes, sub-second with aggressive tuning).
- Promotes itself to Active.
- Sends gratuitous ARP for every owned IP, telling all neighboring devices that the new MAC owns the address.
- Begins forwarding traffic.
What does NOT survive vanilla active/standby (without stateful sync): existing TCP and UDP sessions. Each connection has to re-establish through the new active unit. SSH disconnects, HTTP rebuffers, VPN tunnels reauthenticate. Add stateful failover (the topic of the next article) to preserve sessions, but the base failover mechanism does not.
Prerequisites
The standby-IP requirement bites the most. A /30 outside subnet has no spare address for a standby IP. If your perimeter has /30 transits everywhere, plan a re-IP to /29 before you commit to failover.
Topology and Addressing
The pair we are building:
The failover link uses a link-local /30 (169.254.99.0/30) because nothing else on the network needs to route to it. Pick any private /30 you like; the addresses never leave the link.
Primary Unit Configuration
On the unit you want to be primary:
! 1. The failover link physical interface, no nameif, no IP - reserved for failover.
interface GigabitEthernet0/3
 description LAN/STATE Failover Interface
 no shutdown
 no nameif
 no security-level
 no ip address

! 2. Standby IPs on every data interface (must be in the active interface's subnet)
interface GigabitEthernet0/0
 nameif inside
 security-level 100
 ip address 10.10.0.254 255.255.255.0 standby 10.10.0.253
!
interface GigabitEthernet0/1
 nameif outside
 security-level 0
 ip address 203.0.113.2 255.255.255.248 standby 203.0.113.3
!
interface GigabitEthernet0/2
 nameif dmz
 security-level 50
 ip address 192.168.50.1 255.255.255.0 standby 192.168.50.2

! 3. Failover identity, key, and link configuration
failover lan unit primary
failover lan interface FAIL-LINK GigabitEthernet0/3
failover key <FAILOVER_KEY>
failover replication http

! 4. Failover IP on the failover link (active and standby IP, both on the link)
failover interface ip FAIL-LINK 169.254.99.1 255.255.255.252 standby 169.254.99.2

! 5. Polltimes (defaults shown - tighten for production)
failover polltime unit 1 holdtime 15
failover polltime interface 5 holdtime 25

! 6. Optional: which interfaces to monitor for failover triggering
monitor-interface inside
monitor-interface outside
monitor-interface dmz

! 7. Bring it online
failover
The order matters. Configure the failover link interface (block 1), the data interface standby IPs (block 2), the failover identity and link details (block 3-4), polltimes (block 5), and only then enable failover (failover). Enabling before the link is up triggers the unit into "Active waiting for peer" with no peer to find.
Secondary Unit Configuration
The secondary needs only a minimal bootstrap. Once failover establishes, the primary REPLICATES its full configuration to the secondary, overwriting whatever was there.
! Hostname (just for visibility - replication does NOT change hostname)
hostname ASA-PERIM-SEC
enable password <PASSWORD>

! Failover link interface (must match primary)
interface GigabitEthernet0/3
 no shutdown
 no nameif
 no security-level
 no ip address

! Failover identity, key, link interface, link IP - must match primary
failover lan unit secondary
failover lan interface FAIL-LINK GigabitEthernet0/3
failover key <FAILOVER_KEY>
failover interface ip FAIL-LINK 169.254.99.1 255.255.255.252 standby 169.254.99.2

! Bring it online
failover
That is the full secondary bootstrap. Once failover is enabled, the unit listens on the failover link, hears the primary's hello, authenticates the key, identifies as the secondary, and pulls the primary's config across.
Verifying with show failover
The single most useful command on a failover pair:
ASA-PERIM# show failover
Failover On
Failover unit Primary
Failover LAN Interface: FAIL-LINK GigabitEthernet0/3 (up)
Reconnect timeout 0:00:00
Unit Poll frequency 1 seconds, holdtime 15 seconds
Interface Poll frequency 5 seconds, holdtime 25 seconds
Interface Policy 1
Monitored Interfaces 3 of 1290 maximum
MAC Address Move Notification Interval not set
failover replication http
Version: Ours 9.23(1), Mate 9.23(1)
Serial Number: Ours 9AGRS9XXXX, Mate 9AGRS9YYYY
Last Failover at: 14:23:10 UTC May 10 2026
        This host: Primary - Active
                Active time: 1234 (sec)
                slot 0: ASAv hw/sw rev (/9.23(1)) status (Up Sys)
                  Interface inside (10.10.0.254): Normal (Monitored)
                  Interface outside (203.0.113.2): Normal (Monitored)
                  Interface dmz (192.168.50.1): Normal (Monitored)
        Other host: Secondary - Standby Ready
                Active time: 0 (sec)
                slot 0: ASAv hw/sw rev (/9.23(1)) status (Up Sys)
                  Interface inside (10.10.0.253): Normal (Monitored)
                  Interface outside (203.0.113.3): Normal (Monitored)
                  Interface dmz (192.168.50.2): Normal (Monitored)
Read top to bottom. Failover On is the must-be-line. Failover LAN Interface: ... (up) means the failover link is alive. The Version and Serial Number lines confirm both units are on the same software and identify each. The This host: Primary - Active and Other host: Secondary - Standby Ready are the success state. Each interface should show Normal (Monitored); anything else (Failed, No Link, Testing) is a problem on that interface.
show failover state for the One-Liner
ASA-PERIM# show failover state
                This host -   Primary
                              Active           None
                Other host -  Secondary
                              Standby Ready    None

====Configuration State===
        Sync Done
====Communication State===
        Mac set
Three things to like: This host Active, Other host Standby Ready, Configuration State Sync Done. If Sync Done is missing or shows Sync Failed, the secondary's startup config diverged from what the primary tried to push - typically a license or interface mismatch.
show failover history: The Transition Log
ASA-PERIM# show failover history
==========================================================================
From State                 To State                   Reason
==========================================================================
14:22:55 UTC May 10 2026
Negotiation                Just Active                Other unit is not active
14:22:55 UTC May 10 2026
Just Active                Active Drain               Other unit is not active
14:22:55 UTC May 10 2026
Active Drain               Active Applying Config     Active unit
14:22:55 UTC May 10 2026
Active Applying Config     Active Config Applied      Active unit
14:22:55 UTC May 10 2026
Active Config Applied      Active                     Active unit
==========================================================================
This is the postmortem record. Every state transition the unit went through, with timestamps and reasons. After a failover event, this is the first thing to read - it tells you the moment of failure and why the unit promoted (Comm Failure, Interface Down, Power Loss, etc.).
Testing the Failover
Before you trust failover for the first time, exercise it deliberately. Two test scenarios:
- Manual switchover. On the active unit:
no failover active. The unit transitions to Standby, the peer transitions to Active. Run a continuous ping from a client; you should see at most a single dropped packet. After the test,no failover activeon the (formerly-)standby to fail back. Document the behavior in your maintenance runbook. - Failover-link disconnect. Pull the failover cable. The active stays Active. The standby goes to "Failed" (because it sees no hellos). Reconnect; both units should resync within polltime. Do not simulate this by disabling the failover-link interface via CLI - that triggers a different code path. The cable pull is the realistic test.
Avoid the third "tempting" test: powering off the active unit. It works, but it leaves the standby Active and the formerly-active in a state where it might come back as Active too if the failover link is slow to converge. Always do power-off testing in a maintenance window with two operators on console.
Polltime Tuning
Default polltimes give a worst-case failover detection of 15 seconds (1-second poll, 15-second hold). For most environments, that is fine. For latency-sensitive workloads, tighten:
failover polltime unit msec 200 holdtime msec 800
failover polltime interface msec 500 holdtime 5
200 ms unit poll with 800 ms hold gives sub-second failover detection. Below 200 ms is supported but increases CPU load on both units; only do it if you know you need it. Interface polltime should remain at 500 ms or higher - lower values cause spurious interface flaps.
Lab Constraints (and Production Equivalents)
Two constraints surfaced in the PingLabz ASA reference lab that are worth flagging:
- ASAv refuses Management0/0 as the failover LAN interface. The ASA virtual platform explicitly disallows the management interface for the failover LAN role with the error
Management interface cannot be configured as failover on this platform.Use a regular GigabitEthernet, as shown in the configs above. On physical ASA models this restriction does not apply. - /30 outside subnets do not have room for a standby IP. A /30 has only 4 addresses (network, broadcast, ISP next-hop, ASA active). Failover requires a standby IP on the same subnet. Re-IP to /29 - which gives you 6 usable addresses - or migrate to a /28 if the upstream allows. The configs above assume /29 on outside (203.0.113.0/29).
Home Lab: Failover VLAN Mismatch with Carrier Up
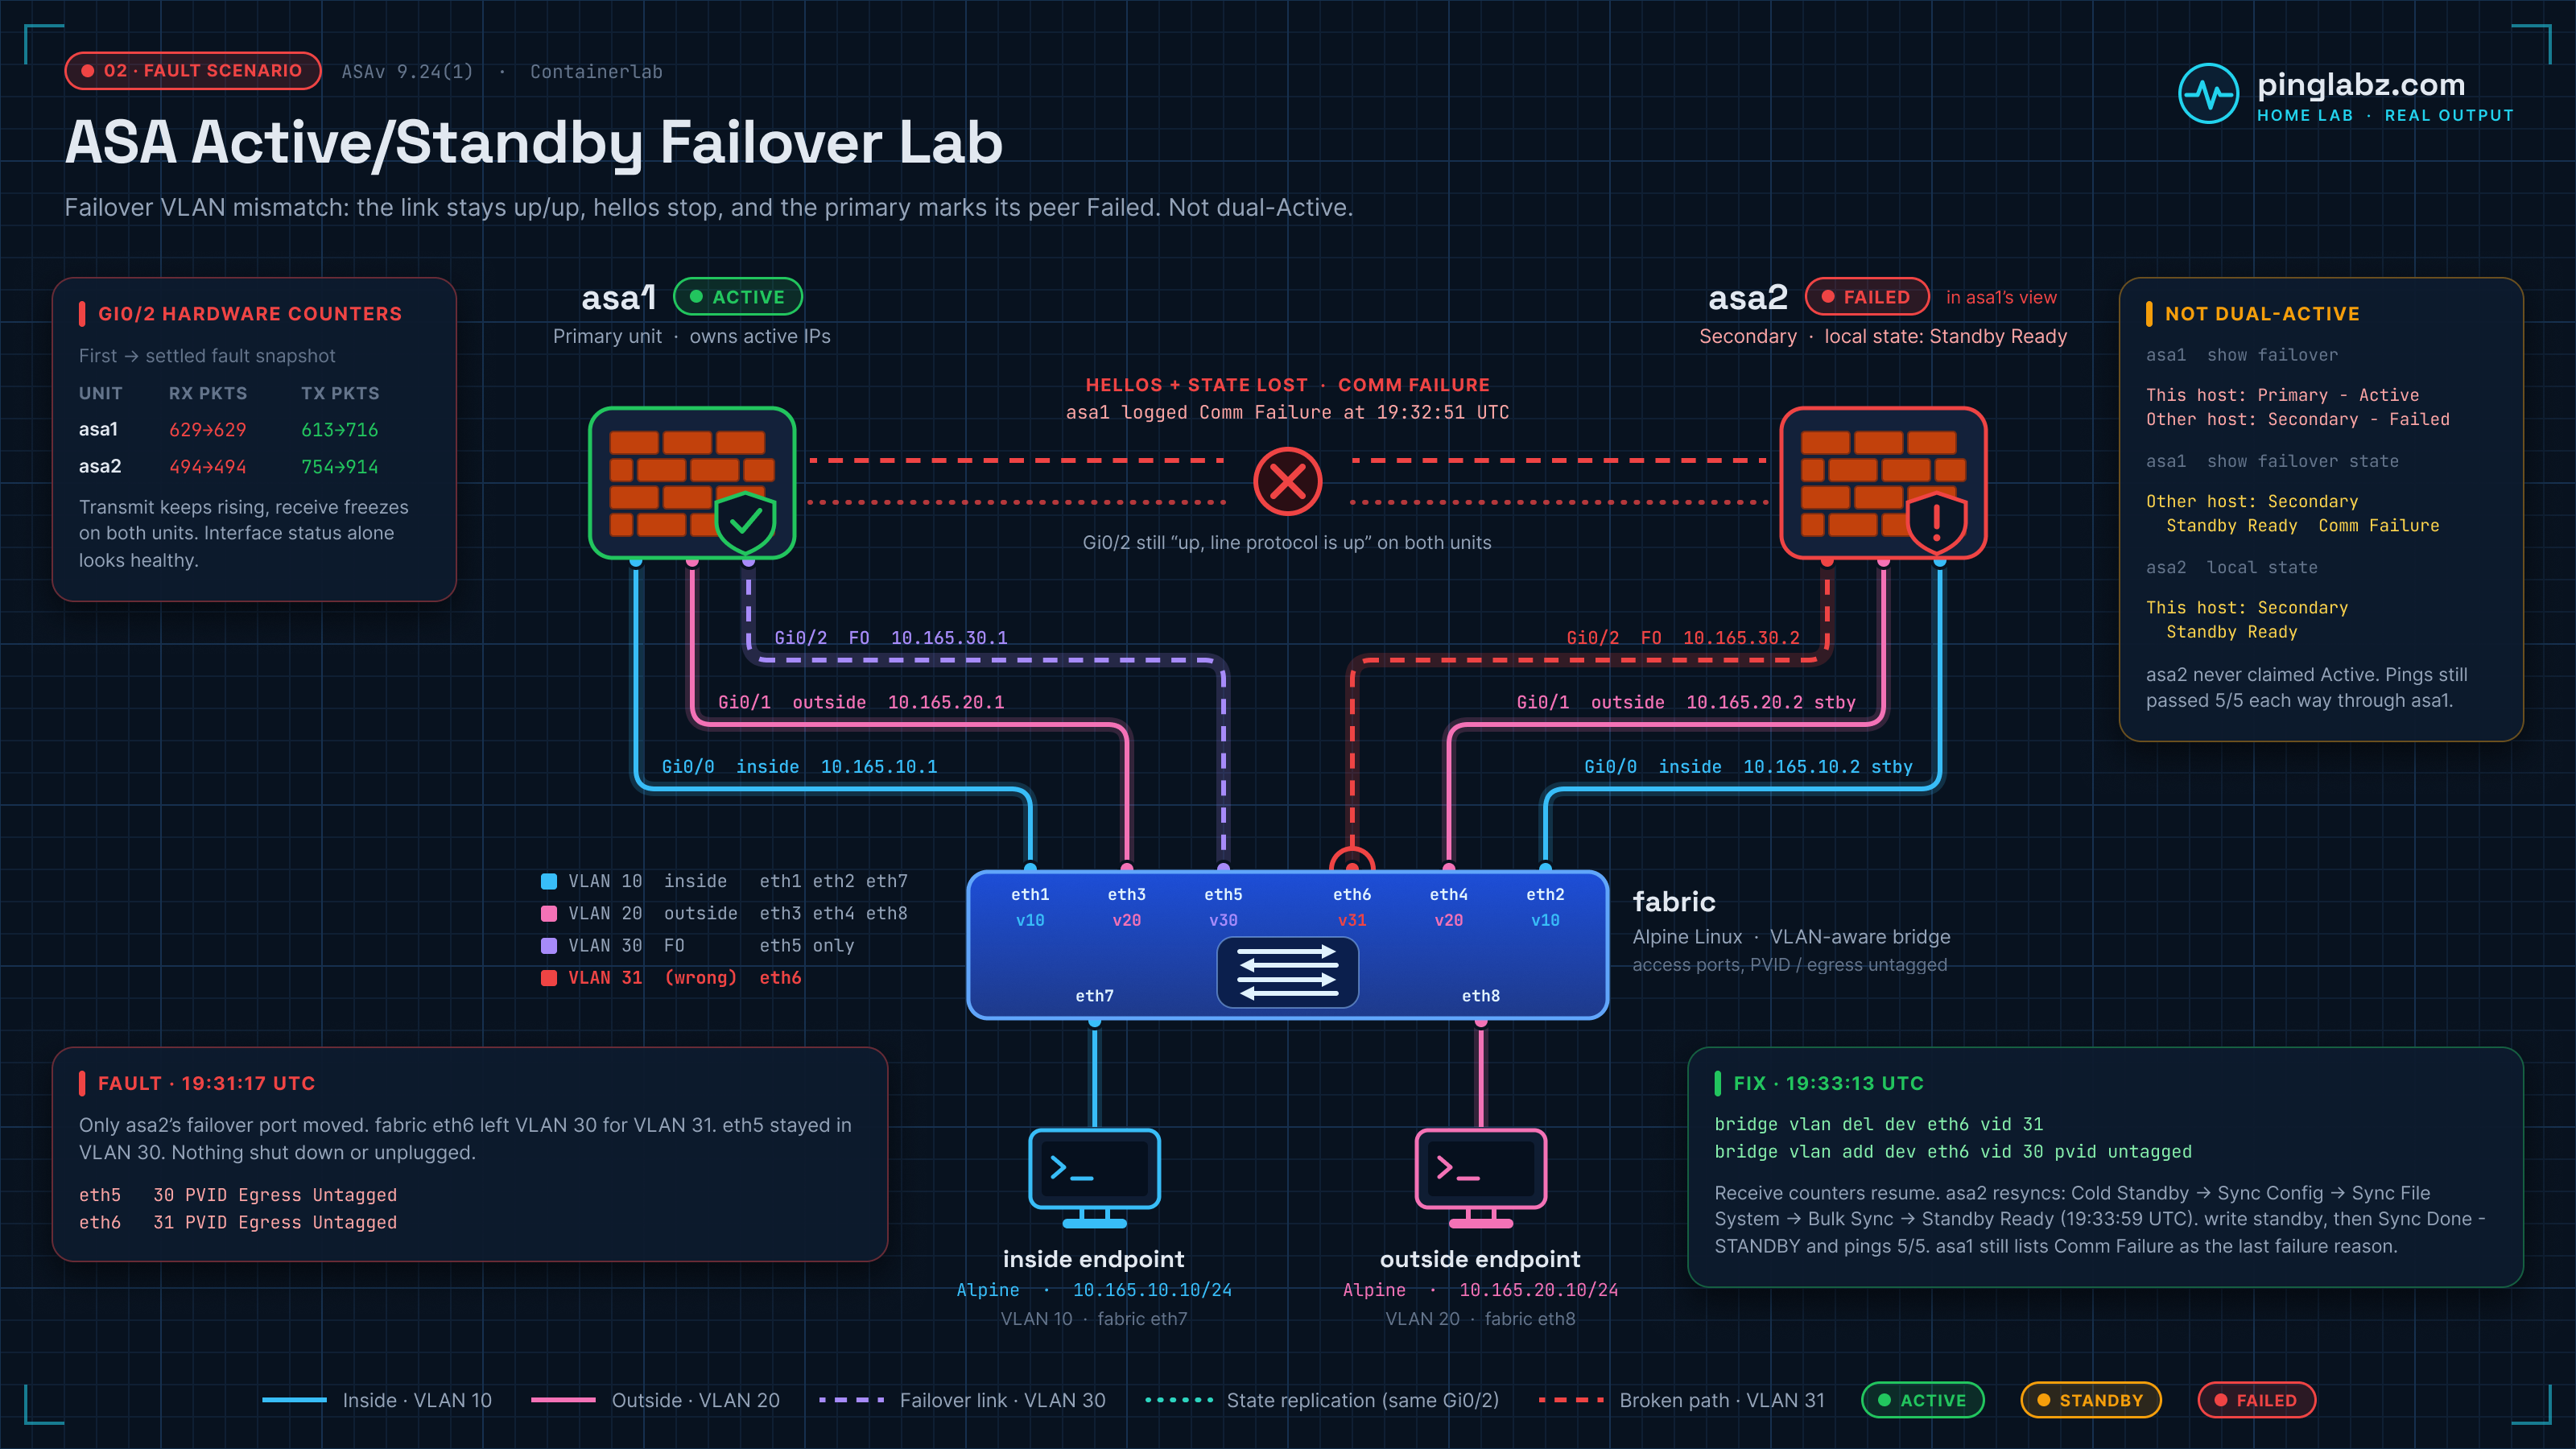
The failover link stayed physically up, but the primary stopped hearing its peer. In this ASAv 9.24(1) run, moving the secondary's failover-facing switch port into the wrong VLAN produced failover communication loss, not dual Active. The primary remained Active and reported the secondary as Failed; the secondary still reported itself as Standby Ready.
Before that fault, the pair synchronized, completed a controlled role handoff, and passed endpoint traffic in both directions. Restoring the VLAN brought peer communication and synchronization back. The excerpts below come from the recorded run on 17 October 2026; ... marks omitted output.
A Separate Address Plan for the Test
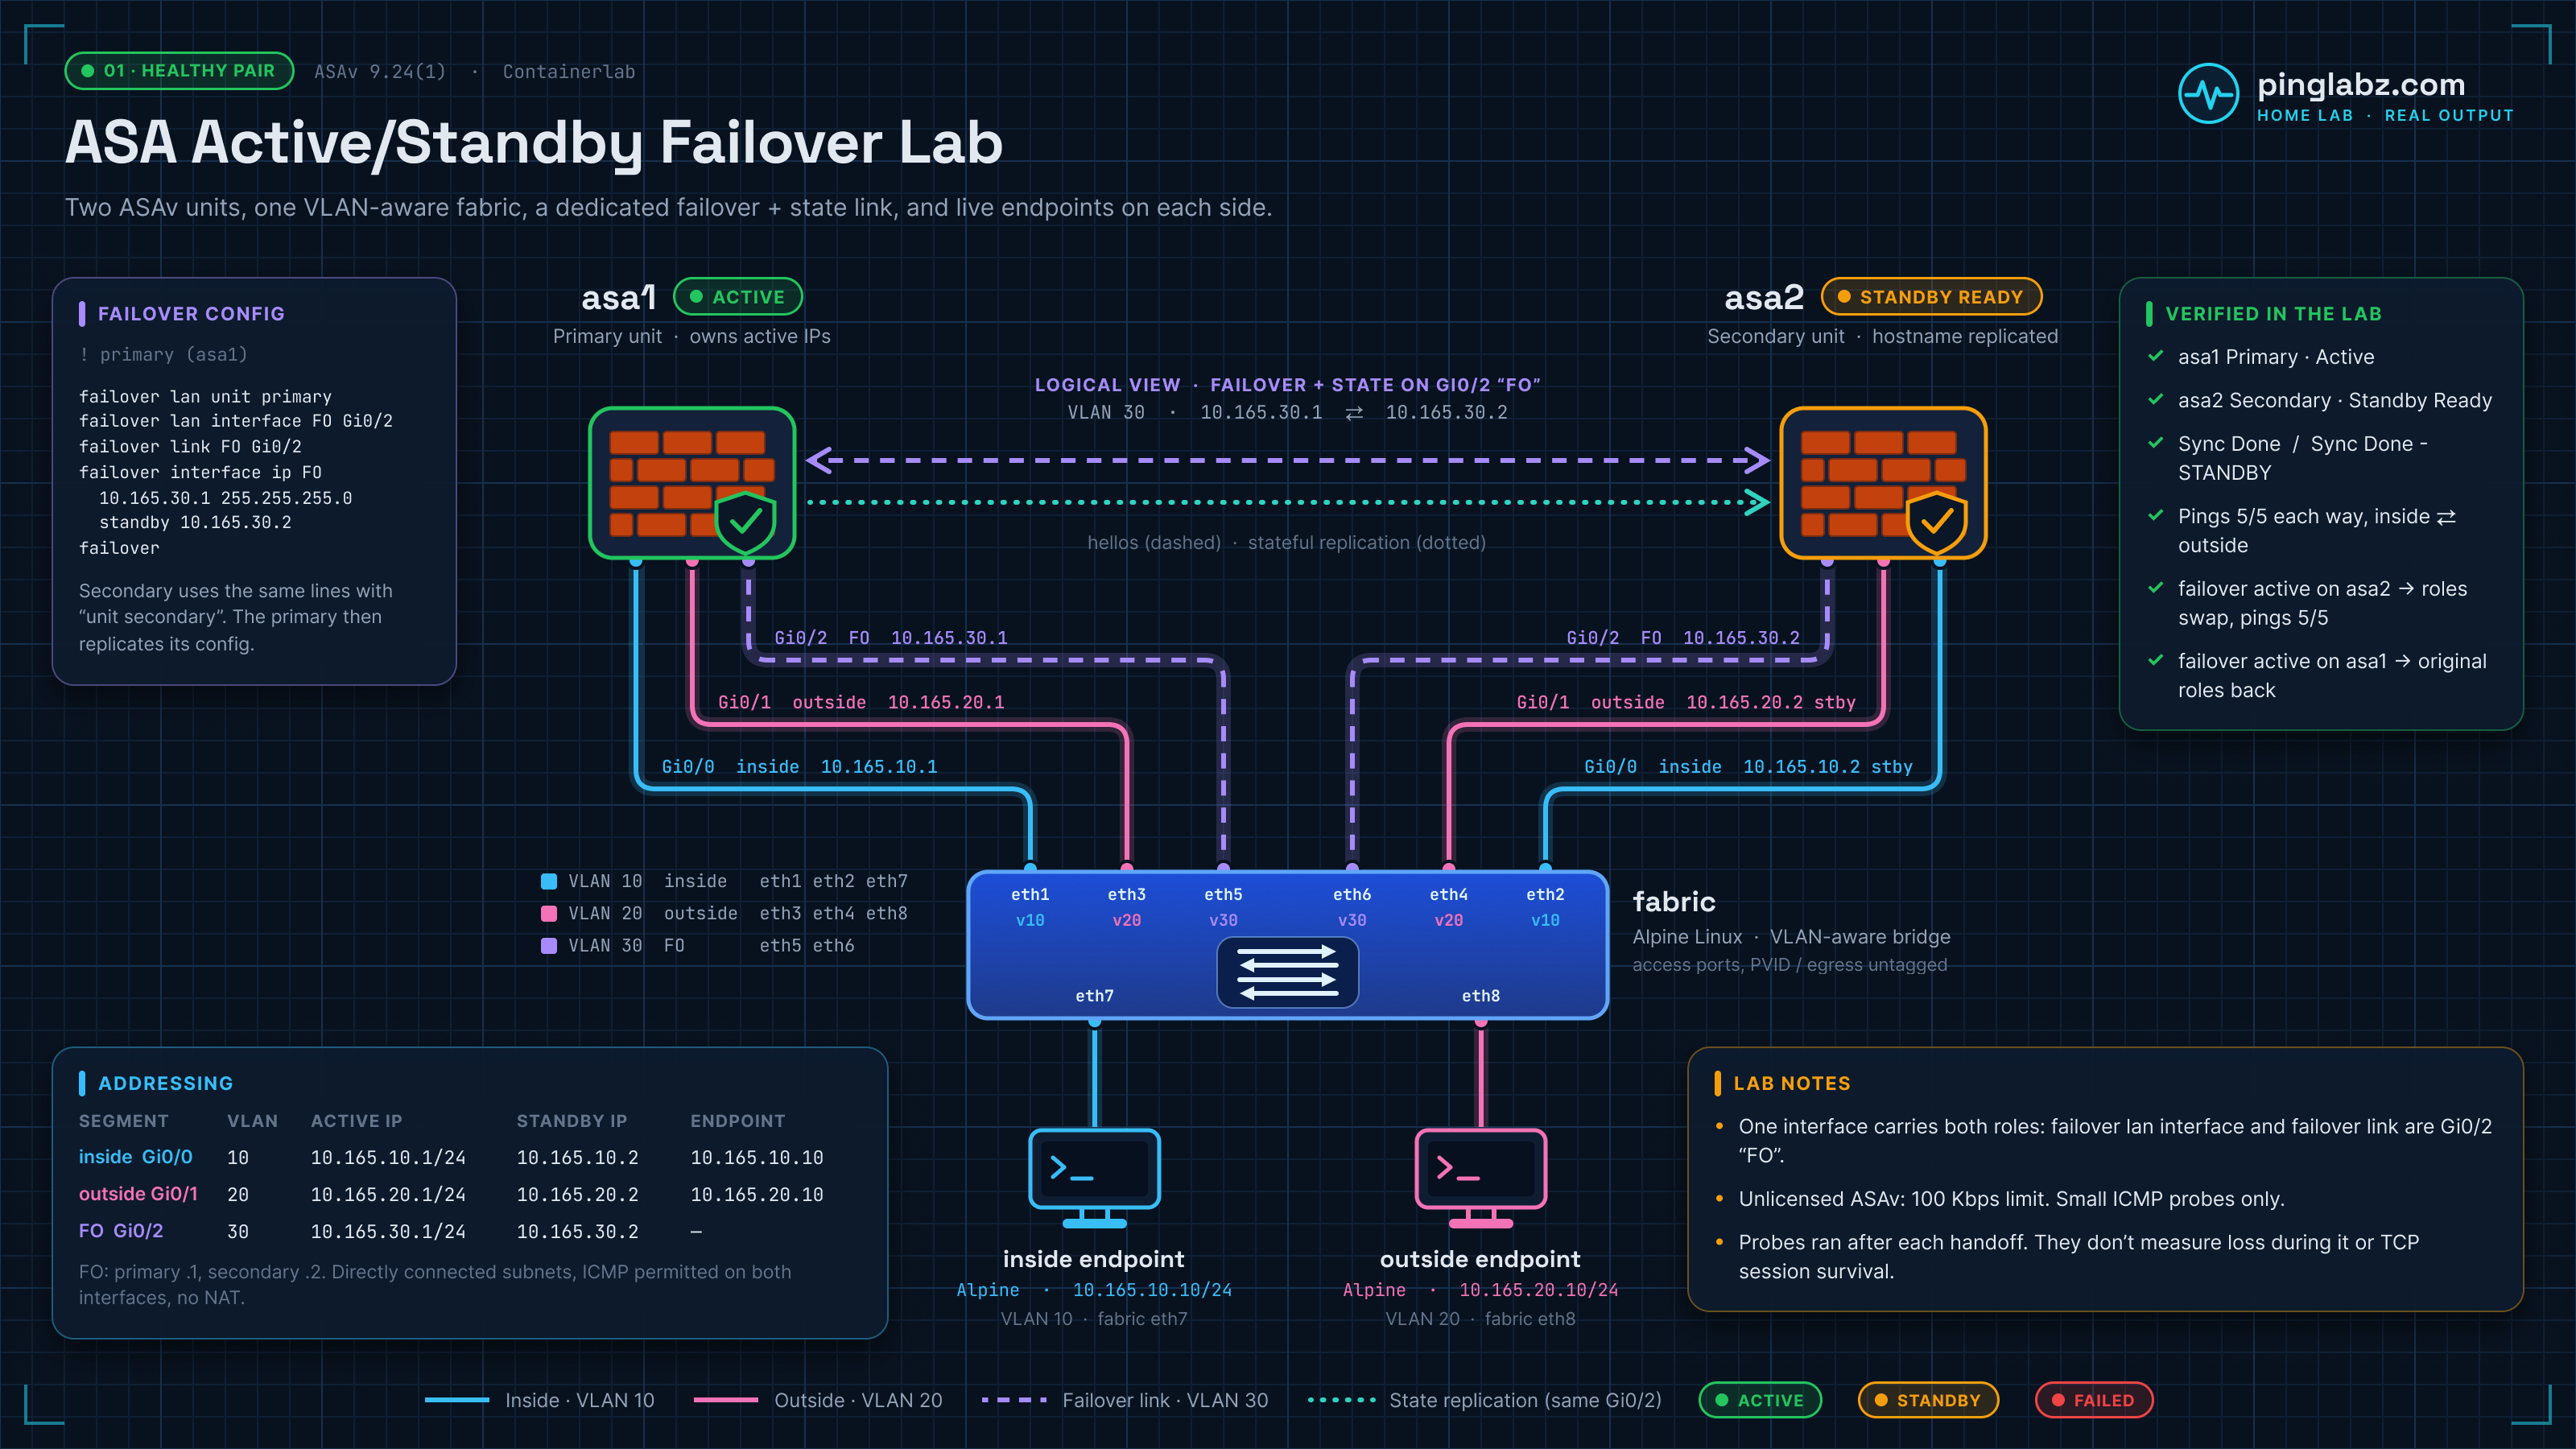
This five-node topology, built in my home lab, used two ASAv 9.24(1) guests, an Alpine fabric switch, and inside/outside Alpine endpoints. Its addressing differs from the reference configuration above.
| Segment | ASAv interfaces | Fabric access ports | Addressing |
|---|---|---|---|
| Inside, VLAN 10 | Both Gi0/0 | eth1 = asa1; eth2 = asa2; eth7 = inside endpoint | Active 10.165.10.1/24, standby .2, endpoint .10 |
| Outside, VLAN 20 | Both Gi0/1 | eth3 = asa1; eth4 = asa2; eth8 = outside endpoint | Active 10.165.20.1/24, standby .2, endpoint .10 |
| Failover/state, VLAN 30 | Both Gi0/2 | eth5 = asa1; eth6 = asa2 | Primary 10.165.30.1/24, secondary 10.165.30.2/24 |
The fabric used a VLAN-aware Linux bridge inside its own network namespace. Inside and outside were directly connected ASA networks with explicit ICMP permits on both interfaces. These probes needed neither NAT nor an external default route. Both failover communication and state replication used Gi0/2, named FO.
Verify Sync and Exercise the Handoff
Read both units with show failover and show failover state before changing anything. The baseline was asa1 Primary/Active and asa2 Secondary/Standby Ready. On asa1, the state excerpt was:
This host  -   Primary
               Active         None
Other host -   Secondary
               Standby Ready  None

====Configuration State===
	Sync Done
The secondary independently reported Standby Ready and Sync Done - STANDBY. Baseline endpoint probes also passed 5/5 each way: ping -n -c 5 -W 2 10.165.20.10 from inside, and ping -n -c 5 -W 2 10.165.10.10 from outside.
To exercise the pair, the recorded test issued failover active on asa2:
asa2-serial# failover active
 failover active

	Switching to Active
Asa2 then reported itself Active and asa1 Standby Ready:
This host  -   Secondary
               Active         None
Other host -   Primary
               Standby Ready  None
Endpoint probes after that handoff passed 5/5 in each direction:
--- 10.165.20.10 ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4004ms
...
--- 10.165.10.10 ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4002ms
The test then issued failover active on asa1 and verified the original roles before injecting the fault. These were probes after the transition; they do not measure packet loss during the handoff or prove that an established TCP session survived.
Move Only the Secondary Failover Port to VLAN 31
At 19:31:17 UTC, the saved lab helper, bash scripts/failover_vlan.sh fault, removed fabric eth6 from VLAN 30 and added it to VLAN 31 as PVID/egress untagged. Run that helper from the lab directory only after verifying the healthy baseline. Eth5 stayed in VLAN 30. Neither ASA interface was shut down, and neither link was removed. The fabric recorded:
eth5              30 PVID Egress Untagged
eth6              31 PVID Egress Untagged
...
eth5@if455       UP             aa:c1:ab:c6:d4:83 <BROADCAST,MULTICAST,UP,LOWER_UP>
eth6@if453       UP             aa:c1:ab:f6:bb:03 <BROADCAST,MULTICAST,UP,LOWER_UP>
By the settled fault snapshot, asa1's show failover reported:
	This host: Primary - Active
...
	Other host: Secondary - Failed
Its immediately following show failover state retained Standby Ready for the peer, alongside the last failure reason Comm Failure:
This host  -   Primary
               Active         None
Other host -   Secondary
               Standby Ready  Comm Failure             19:32:51 UTC Oct 17 2026

====Configuration State===
	Sync Done
Those commands were consecutive snapshots, not an atomic view. Preserve the difference when diagnosing the failure. The Sync Done line describes the previously completed configuration sync; it did not establish that the isolated link was currently healthy.
On asa2, the local state still read:
This host  -   Secondary
               Standby Ready  None
Other host -   Primary
               Active         None
The secondary never reported itself Active during this fault. Read its local state alongside the primary's peer-failure report before calling this a dual-Active event.
Run show interface GigabitEthernet0/2 on each unit as well. Both recorded the same physical status:
Interface GigabitEthernet0/2 "FO", is up, line protocol is upThe hardware packet counters exposed the communication loss despite that up/up status. Between the first and settled fault snapshots:
| Unit | Hardware receive packets | Hardware transmit packets |
|---|---|---|
| asa1 | 629 → 629 | 613 → 716 |
| asa2 | 494 → 494 | 754 → 914 |
Transmit counts rose while receive counts froze on both units. Endpoint pings still passed 5/5 each way through the active primary. Working client traffic alone would have missed the broken failover path.
Restore VLAN 30 and Verify Recovery
At 19:33:13 UTC, bash scripts/failover_vlan.sh fix removed eth6 from VLAN 31 and restored its VLAN 30 PVID/untagged membership:
eth5              30 PVID Egress Untagged
eth6              30 PVID Egress Untagged
Receive counters resumed increasing. The secondary's history recorded Cold Standby, Sync Config, Sync File System, Bulk Sync, and finally Standby Ready at 19:33:59, with the reason Resyncing due to IP traffic issue.
The test also ran write standby on the active unit to force complete configuration replication, then waited for the standby to return Ready. That command replicates configuration; the configurations were saved separately with write memory.
After replication, asa1 reported:
This host  -   Primary
               Active         None
Other host -   Secondary
               Standby Ready  Comm Failure             19:32:51 UTC Oct 17 2026

====Configuration State===
	Sync Done
Asa2 reported:
This host  -   Secondary
               Standby Ready  None
Other host -   Primary
               Active         None

====Configuration State===
	Sync Done - STANDBY
The primary retained Comm Failure as its last failure reason. Recovery was established by the current roles, resumed reception, completed replication, and fresh traffic checks, rather than by expecting that history field to clear.
The final endpoint tests again passed in both directions:
--- 10.165.20.10 ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4060ms
...
--- 10.165.10.10 ping statistics ---
5 packets transmitted, 5 received, 0% packet loss, time 4004ms
ASAv Wrapper and Console Constraints
The wrapper's management SSH forwarding targeted guest 10.0.0.15. Once failover assigned the standby management address 10.0.0.16, that forwarding no longer reached the standby. This access limitation could look like a dead peer from an SSH client. The run used each container's serial console on TCP 5000 to inspect both units independently after pairing. Replication also gave both guests the same hostname, so the recorder's unit label mattered when reading the output.
Both appliances performed a platform-discovery reboot during first boot. Startup completed about 8 minutes 36 seconds and 8 minutes 46 seconds after the two units started; failover configuration followed readiness. The ASAv boot and first-packet walkthrough covers that startup sequence in more detail.
This unlicensed image reported a 100 Kbps throughput limit. The small ICMP tests establish forwarding and role behavior for this run, without measuring production throughput, failover latency, or TCP session preservation. If peer communication has recovered but client traffic still fails, the ASA ASP-drop walkthrough covers the next data-plane checks.
Key Takeaways
Active/standby failover is straightforward: identical hardware, dedicated failover link, matching failover key, standby IP on every monitored data interface. The primary boots to Active and the secondary boots to Standby Ready; show failover is the single command that tells you whether the pair is healthy. Add stateful failover from the next article to also preserve TCP sessions across the failover. And for the failure modes - both units active, neither active, slow promotion - common outage scenarios walks the diagnostic for each. The full Cisco ASA reference cluster has the rest of the perimeter playbook.